Renting NVIDIA or AMD Instinct GPU capacity by the hour suits UK enterprises with unpredictable or short-lived AI training workloads. Buying an NVIDIA DGX system pays back faster once a team runs GPUs for more than roughly half the year. Live pricing checked directly against AWS's and Microsoft's own pricing APIs shows UK cloud regions charging 25% to 30% more per GPU-hour than US regions for the identical instance, so region and utilisation both belong in the decision, not just the headline hourly rate.
Key pointers
- AWS's London GPU instances cost 30% more per hour than the identical instance in US East; Azure's UK South region costs 25% more than its US East equivalent, both checked today against each provider's own pricing data.
- Renting an 8-GPU H100 node from AWS in London around the clock for a year costs roughly £467,933; a comparable NVIDIA DGX H100 system is estimated at around £261,291, so sustained year-round use tips the balance towards buying.
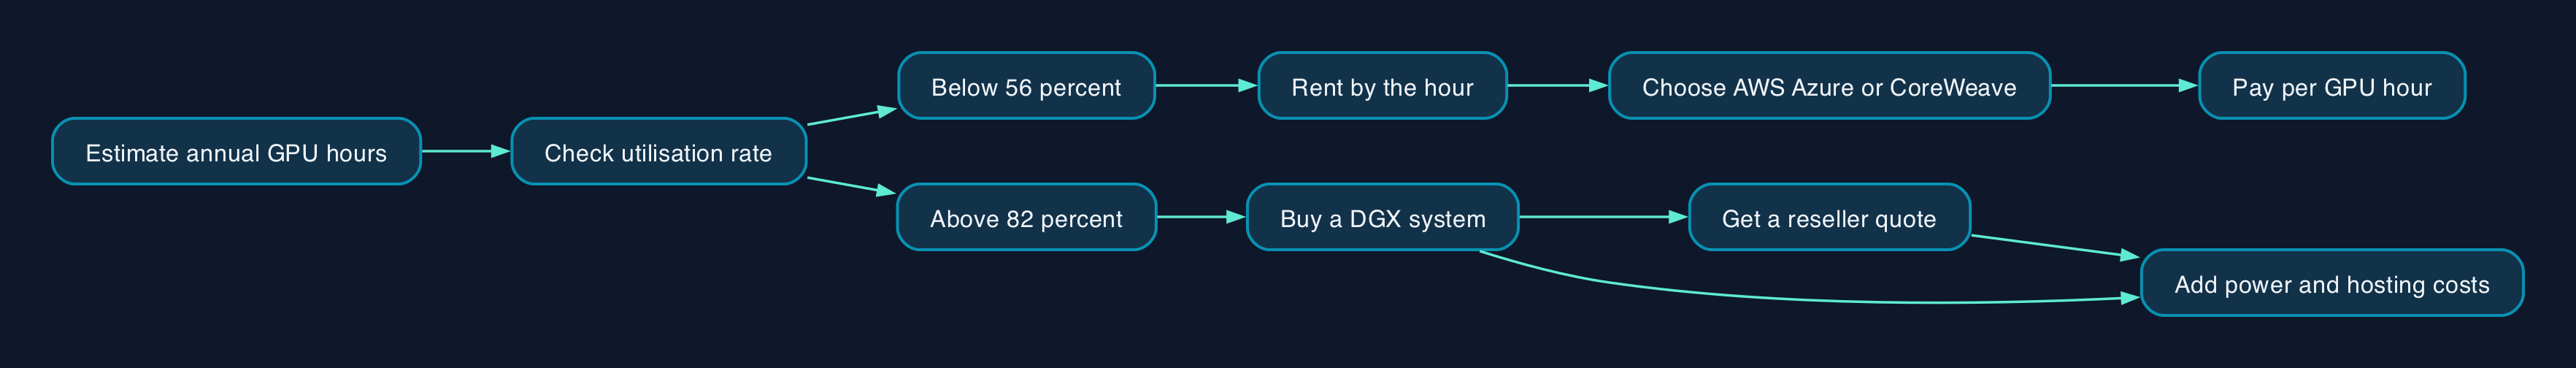
- Break-even against that same AWS London rental falls at roughly 56% utilisation for a DGX H100 and 82% for the newer, pricier DGX B200 (estimated £384,472).
- AMD Instinct MI300X capacity is available directly from Azure's UK South region at £5.52 per GPU-hour, cheaper than Azure's own H100 instance at £11.31, for workloads that fit its larger 192GB memory pool.
- NVIDIA does not publish a DGX list price. Get a written quotation from a reseller covering hardware, three years of support and installation before budgeting a figure.
- A DGX B200 draws up to 14.3kW at full load; running one continuously at 2026 UK industrial electricity rates adds roughly £24,800 to £31,100 a year in power alone, before VAT.
- CoreWeave, the cheapest on-demand H100 rate checked here, now runs its GPU infrastructure from two UK sites, in Crawley and London Docklands, so cost is not the only reason to look beyond AWS and Azure.
- Spot pricing cuts the hourly rate sharply, Azure's H100 spot rate is about 81% below its on-demand price, but capacity can be reclaimed by the provider mid-job.
What renting and buying actually mean for UK AI teams
A head of AI infrastructure choosing between renting and buying is really choosing where fixed cost sits. Renting turns GPU access into an operating expense billed per hour, with no capital outlay, no rack space and no power contract of your own. Buying a DGX system turns it into a capital asset that sits in your own data centre or a colocation suite, with a fixed cost regardless of how many hours it actually trains models.
Neither option removes the work. Rented capacity still needs someone to manage cluster scheduling, data movement and cost control, or the hourly bill grows unpredictably. A bought system still needs power, cooling, networking, a support contract and staff who can rack, patch and troubleshoot it. The decision is less "cloud versus on-premises" and more "who carries the utilisation risk", the cloud provider, who prices that risk into the hourly rate, or your own business, which carries it directly once the hardware is bought.
How hourly GPU rental pricing works
Hyperscaler pricing for NVIDIA H100 GPUs is public and checkable. AWS's EC2 P5 instances pack 8x NVIDIA H100 GPUs (80GB HBM3 each) into a single node. Checked live against AWS's own pricing API on 29 September 2026, that node costs $55.04 an hour on-demand in US East (N. Virginia) and $71.552 an hour in London (eu-west-2), a 30.0% premium for the identical hardware in the UK region. Microsoft's equivalent, the ND96isr H100 v5, costs $98.32 an hour in East US and $122.90 an hour on-demand in UK South, both Microsoft's own USD retail prices via the Azure Retail Prices API, a 25.0% premium checked the same day. Azure also returns a GBP reference figure for the UK South instance, £90.48 an hour, but Microsoft's own documentation for the API states plainly that non-USD prices are an estimate for budgeting rather than the price actually billed.
Neither premium is arbitrary. UK and EU data centre capacity for GPU-class power density is scarcer than in US hyperscale regions, and both AWS and Azure price each region independently rather than averaging globally. A UK enterprise that genuinely needs UK data residency has to accept that premium; one that does not could train in a US region and accept extra network latency instead.
CoreWeave, a specialist "neocloud", lists its 8x H100 node at $49.24 an hour on-demand, cheaper than either hyperscaler's on-demand rate, and its pricing page publishes this same $49.24 rate for both a North America region and a Europe region, with only the spot price differing slightly between the two ($19.71 in North America against $19.51 in Europe). CoreWeave confirmed in January 2025 that it had brought its first two UK sites online, deploying its GPU infrastructure into colocation facilities run by Digital Realty in Crawley and Global Switch in London Docklands, backed by over £1 billion of UK investment, and naming London its European headquarters. A UK enterprise weighing CoreWeave against AWS or Azure on data residency grounds should confirm with CoreWeave directly which region a workload lands in, since the pricing page does not break "Europe" down by country.
Spot pricing changes the calculation further. Azure's H100 spot rate in East US is $18.17 an hour, about 81% below the $98.32 on-demand rate, because it uses spare capacity that Azure can reclaim with little notice. Spot suits fault-tolerant training runs that checkpoint frequently; it is a poor fit for a single long run that cannot be interrupted without losing progress.
What an NVIDIA DGX system costs to buy
NVIDIA does not publish a DGX price list. Its own DGX B200 product page gives full specifications, 8x Blackwell GPUs, 1,440 GB of GPU memory, up to 14.3kW of power draw, and confirms "Three-year Enterprise Business-Standard Support for hardware and software" is included, but shows no price. Boston Limited, a UK NVIDIA partner, lists the same system with identical specifications and no price either, offering pre-purchase testing through its own labs and directing buyers to "speak to our specialists". Every DGX purchase in the UK goes through this kind of quotation process, not a checkout page.
Independent market tracking gives a working estimate. A complete DGX H100 system, the previous Hopper-generation appliance, is reported at roughly $300,000 to $400,000 (about £224,000 to £298,500 at today's rate). The newer DGX B200 is reported at close to $515,000 (about £384,472). Treat both as estimates for budgeting purposes, not quoted prices; a genuine reseller quotation will vary with configuration, support level, delivery lead time and any discount negotiated, and the current chip and memory shortage Compare the Cloud has covered separately is adding to hardware lead times across the market.
AMD Instinct as the rental alternative
AMD's Instinct MI300X is the most credible alternative to NVIDIA for rented capacity, and it is genuinely available in a UK region. Azure's ND96isr MI300X v5 instance, 8x MI300X GPUs with 192GB of HBM3 memory each, prices at $60.00 an hour on-demand directly from UK South (a Microsoft GBP reference of £44.17), working out to £5.52 per GPU-hour, cheaper than Azure's own H100 instance at £11.31 per GPU-hour. Interestingly, this SKU did not appear as a standalone virtual machine in Azure's East US pricing at the time of checking, only through a separate managed-hosting meter, so UK South is a genuine first-class region for this accelerator rather than a US product carrying a regional premium.
The larger memory pool matters for models that do not fit comfortably in an H100's 80GB. It means fewer GPUs needed for a given model size, which can offset a per-GPU price difference. Set against that is NVIDIA's dominant position in AI training tooling; most training frameworks, libraries and pre-built container images assume CUDA, NVIDIA's software stack, as the default, and moving a working pipeline to AMD's ROCm stack is real engineering work, not a configuration change. A team already committed to CUDA-based training code should budget for that migration effort before assuming the lower headline rate is the whole saving.
Comparing the total cost of renting and buying
The arithmetic below uses AWS's London on-demand rate as the rental baseline, because it is the cheapest UK-region hyperscaler figure this article verified, and compares it with the estimated DGX purchase prices above. All figures are before VAT and exclude power, networking, staff time and rack space, which are separate costs that apply mainly to the "buy" side.
Assumptions: DGX H100 estimated at $350,000 (midpoint of the $300,000 to $400,000 range), DGX B200 estimated at $515,000, both converted at 0.7465 USD/GBP. AWS London on-demand rate of $71.552 an hour converts to £53.42 an hour; a full year of continuous use is 8,760 hours.
- One year of continuous AWS London rental (8x H100, on-demand, no reserved discount): £53.42 x 8,760 hours = £467,933.
- Estimated DGX H100 purchase price: £261,291. Break-even against continuous AWS London rental: £261,291 / £53.42 = 4,891 hours, or 56% of a year.
- Estimated DGX B200 purchase price: £384,472. Break-even against the same rental rate: £384,472 / £53.42 = 7,198 hours, or 82% of a year.
In plain terms, a training programme that keeps 8 GPUs busy for more than about half the year already beats continuous on-demand rental with a DGX H100, and the newer, pricier DGX B200 needs closer to five-sixths of the year in use before it does the same. A programme that runs GPUs for a few weeks a quarter, or in unpredictable bursts around release cycles, will struggle to reach either threshold and is better served renting. Reserved or committed cloud pricing would improve the rental side of this comparison; none of the figures above include a multi-year discount, because those contracts require negotiation and are not published list prices.
Vendor and option comparison
| Option | UK availability | On-demand rate (per GPU-hour) | Best suited to | Who manages it |
|---|---|---|---|---|
| AWS EC2 P5 (NVIDIA H100) | London region, live pricing checked | £6.68 | Bursty or short training runs needing UK residency | AWS manages hardware; your team manages the workload |
| Azure ND H100 v5 | UK South, live pricing checked | £11.31 | Teams already standardised on Azure and Microsoft support | Microsoft manages hardware; your team manages the workload |
| Azure ND MI300X v5 (AMD Instinct) | UK South, live pricing checked | £5.52 | Memory-bound models where fewer, larger-memory GPUs help, if ROCm tooling is acceptable | Microsoft manages hardware; your team manages the workload and any CUDA migration |
| CoreWeave (NVIDIA H100) | UK sites running since 2025 (Crawley, London Docklands) | £4.59 | Cost-sensitive training where a specialist neocloud's support model suits the team | CoreWeave manages hardware; your team manages the workload |
| Buy an NVIDIA DGX H100 | Quoted by UK resellers, est. £261,291 | n/a, capital cost | Sustained training at roughly 56%+ utilisation over a year | Your team, or a managed-hosting partner, runs and maintains it |
| Buy an NVIDIA DGX B200 | Quoted by UK resellers, est. £384,472 | n/a, capital cost | Sustained, large-scale training at roughly 82%+ utilisation over a year | Your team, or a managed-hosting partner, runs and maintains it |
No option wins outright. A team unsure of its actual utilisation should start on rented capacity, measure GPU-hours used over two or three months, and only then compare that measured run rate against the break-even figures above.
Questions to ask before you commit
- What is our realistic GPU utilisation over a full year, measured in hours, not guessed as a percentage?
- If renting, does the provider's contract confirm which specific country or facility a workload runs in, rather than a regional label such as "Europe"?
- If buying, what does the reseller's written quotation include, hardware, delivery, installation, racking, and how many years of support, beyond NVIDIA's standard three years?
- What is the total power draw once the system is racked, and has the business's electricity contract, and available site power capacity, been checked against it?
- If considering AMD Instinct, has the training and inference stack actually been tested on ROCm, or does it assume CUDA throughout?
- What happens to committed cloud spend, or an owned system, if the project is cancelled or the model architecture changes and the hardware no longer fits the workload?
- Does the chosen route lock the business into one vendor's software stack in a way that makes switching GPU suppliers later expensive?
Editorial analysis
The clearest signal in this comparison is not which option is cheaper in the abstract, it is that the UK carries a real, measurable premium on rented GPU capacity, 25% to 30% on the two hyperscalers checked here, on top of the usual rent-versus-buy trade-off. That premium alone is a reason for a UK enterprise with sustained training needs to take the buy option more seriously than a US-based peer would, because every hour of rented UK capacity costs proportionately more than it would for that peer. Where utilisation is genuinely uncertain, renting still carries the least risk; a DGX system that sits at 20% utilisation is an expensive way to learn that a project did not need dedicated hardware. The AMD Instinct route deserves a proper trial rather than dismissal on cost grounds alone, but only where the workload's memory profile and the team's tooling both point that way, not simply because the headline rate is lower. CoreWeave's arrival in the UK also means the old assumption that cheaper neoclouds automatically mean US-only hosting no longer holds, and it is worth a call even where AWS or Azure feel like the default choice.
Sources
- Amazon EC2 P5 Instances, AWS
- AWS Price List API, AmazonEC2, us-east-1, AWS, checked 29 September 2026
- AWS Price List API, AmazonEC2, eu-west-2 (London), AWS, checked 29 September 2026
- Azure Retail Prices REST API overview, Microsoft, live queries checked 29 September 2026
- CoreWeave Cloud Pricing, CoreWeave, checked 29 September 2026
- CoreWeave Announces Two Initial Data Centers In The UK Are Now Operational, CoreWeave, 13 January 2025
- NVIDIA DGX B200, NVIDIA
- NVIDIA DGX B200 product page, Boston Limited
- Data Center GPU Prices, Costs, Configs and Price History, IntuitionLabs, 5 September 2026
- Average business electricity prices per kWh in 2026, Utilities Made Simple, 2 September 2026
- 1 USD to GBP currency converter, Xe, checked 29 September 2026
- Memory and Chip Shortage, What UK IT Buyers Can Do Now, Compare the Cloud, 6 August 2026